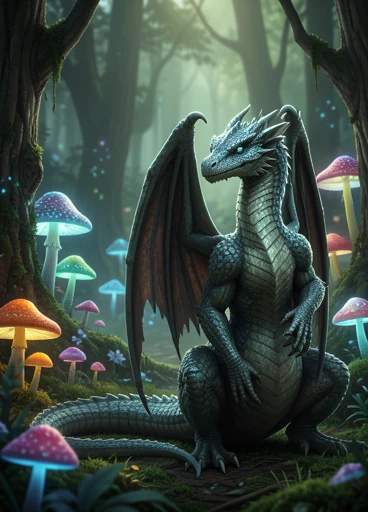
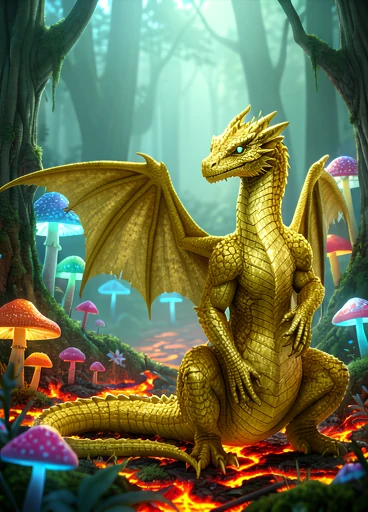
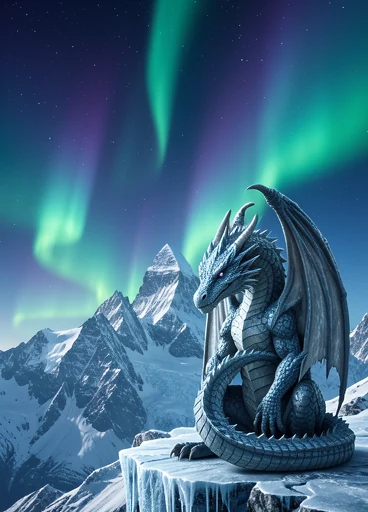
Show one before/after example. Choose which of its edits carry over to your image.
* Both authors contributed equally to this research.
Each example opens with its edits switched on — switch any of them off, or back on, one at a time or together, and watch the result change. The demonstration pair never changes, only the result. Every image here is a real SIA output.
Image analogy copies a change shown by a before/after pair (A, A′) onto a new image B. But one pair usually holds several edits at once, and existing methods transfer all of them — you cannot ask for only some.
We introduce Selective Image Analogy (SIA): the pair stays fixed, and you choose which of its edits to apply. SIA first learns to transfer the whole change, then gains control from a mask over the edit words. The mask acts twice — it weakens the unwanted words in the text embedding, and gates a small adapter to them while the image is generated. The unwanted edits are dropped and the chosen ones stay, even though every edit is still visible in A′, and no new pair is needed for each combination.
The examples play one after another: the slider sweeps across to reveal SIA’s result, then moves on. Hover to pause, or pick one from the row underneath.Tap pause to hold one, or pick one from the row underneath.
Before denoising the mask weakens the suppressed tokens in the text embedding; during denoising it gates the adapter to those same tokens. The demonstration pair and the prompt stay untouched.
Switch an edit off. Its prompt tokens get a 1 in the mask, and ExLoRA acts on those tokens only; everything else is processed exactly as before.
h̃j = (W + Mj · α⁄r BsAs) hj with Mj = 1 only on a dropped edit’s tokens
ExLoRA sees the whole example and the full prompt, every edit named, with the mask on one edit. Its target is the query with only the other edits applied, so it learns to read masked tokens as “do not transfer”. AnaLoRA, trained first on full analogies, keeps carrying everything else.


The prompt still names the dropped edit. For each edit, 64 contrastive prompt pairs, with and without it, are encoded once; the difference of their means is the edit direction d, cached and reused. At inference the dropped edit’s token loses its component along d.
h ← h − λ (h⊤d) d
Our Multi-Edit Analogy Dataset spans creature and non-creature subjects and covers object additions, appearance changes, expression changes, pose changes, background replacements and style transfer. Every sample is filtered with a vision–language model to verify that the desired edits are present and the excluded ones are absent.
Preservation alone is not enough for selective analogy: a method that barely changes the query image scores well on preservation and badly on everything else. SIA leads on retained accuracy, recall and both CLIP directional scores.
| Method | Qwen3-VL-32B | Gemma 3 | CLIP | |||||
|---|---|---|---|---|---|---|---|---|
| Ret. Acc. ↑ | Pres. ↑ | Recall ↑ | Ret. Acc. ↑ | Pres. ↑ | Recall ↑ | Dir. Image ↑ | Dir. Ret. ↑ | |
| RelationAdapter [Gong et al. 2025] | 6.74 | 9.93 | 0.782 | 8.09 | 9.48 | 0.941 | 0.386 | 0.144 |
| VisualCloze [Li et al. 2025] | 7.24 | 8.62 | 0.856 | 8.14 | 9.28 | 0.947 | 0.464 | 0.152 |
| Edit Transfer [Chen et al. 2025] | 2.31 | 9.96 | 0.176 | 5.75 | 9.58 | 0.623 | 0.102 | 0.023 |
| LoRWeB [Manor et al. 2026] | 6.59 | 9.83 | 0.736 | 8.12 | 9.51 | 0.926 | 0.402 | 0.155 |
| SIA (ours) | 8.01 | 9.75 | 0.892 | 8.65 | 9.57 | 0.952 | 0.543 | 0.171 |
@inproceedings{alimohammadi2026sia,
title = {SIA: Selective Image Analogy},
author = {Alimohammadi, Amir and Izadpanah, Kian and
Kariminia, Bardiya and Chrysanthou, Yiorgos and
Mahdavi-Amiri, Ali},
booktitle = {SIGGRAPH Asia 2026 Conference Papers},
year = {2026},
publisher = {Association for Computing Machinery}
}
Questions and requests are welcome — please open an issue on the GitHub repository.